Senate Race in Texas – The Statistical Model by County

What Do 254 Texas Counties Tell Us About the 2026 U.S. Senate Election? A Mathematical Model Examines the Numbers
An analysis of county-level election results uses historical voting totals, statistical formulas and a mathematical model to examine how votes were distributed across Texas in the 2026 U.S. Senate election.
Executive Summary
The analysis of the data show that, whatever may be the cause of the dramatic increase in Democrat votes over that of Republican votes in the Texas U.S. Senate Race between Ken Paxton and James Talarico, the cause is unlikely to be the result of machine manipulation of electronic voting machines.
We searched, county by county, for any sign of mathematical formulaic anomalies, numerical patters, scatter plot patterns, and can find no explanation for the results as they were finalized. It is our conclusion that if the election were manipulated, and we are not making a claim that it was, it was likely not accomplished by electronic means.
What follows is the research we conducted, on full geek display, and presented to you so that you may continue your own research. We outline our methodology, formula & process. We provide you with a spreadsheet to expand with your own data.
Purpose of the Research
Election results are generally reported as statewide totals. Those totals tell us who received the most votes, but they do not necessarily reveal how voting patterns differed from one part of the state to another.
Texas has 254 counties, ranging from small rural communities with relatively few votes to major metropolitan counties with hundreds of thousands of ballots. Examining the state as a single voting population can conceal important differences among those counties.
This research takes a closer look.
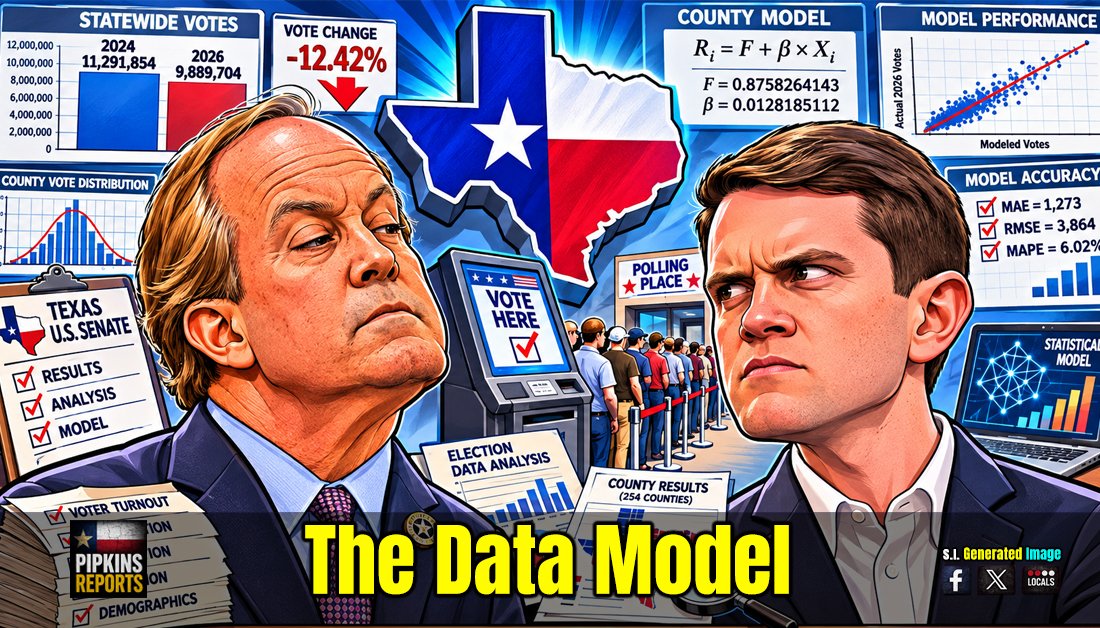
Using the 2024 and 2026 U.S. Senate election results, we developed a mathematical model to examine the distribution of votes across all 254 Texas counties. The model uses each county’s 2024 voting total, the change in statewide voting volume between the two elections, and a statistical adjustment based on county size to calculate an expected 2026 vote total for every county.
Those calculated totals are then compared with the actual reported 2026 results.
The purpose is to establish a consistent mathematical baseline, identify where actual county totals differ from modeled expectations, and provide a foundation for additional research into population changes, voter participation, migration and other factors that may influence election results.
This is a retrospective statistical analysis. It uses the known 2026 statewide vote total to establish the model’s overall allocation. It is not an independent prediction of an election result, and it does not attempt to identify how individual voters cast their ballots.
The Data: Comparing Two Senate Elections
The analysis begins with the total votes reported in the Texas U.S. Senate contests in 2024 and 2026.
| Election | Total Statewide votes |
|---|---|
| 2024 U.S. Senate – Ted Cruz / Colin Allred | 11,291,854 |
| 2026 U.S. Senate – Ken Paxton / James Talarico | 9,889,704 |
| Change | -1,402,150 |
**The Statewide votes are for the entire election and include third party candidates.
Download the Spreadsheet for Analysis.
The 2026 election produced 1,402,150 fewer Senate votes than the 2024 election, a decrease of approximately 12.42%.
The research uses county-level results for all 254 Texas counties. Each county’s 2024 vote total provides the historical baseline, while its reported 2026 total provides the actual result against which the model is measured.
The 2026 figures come from a Texas Secretary of State election-results feed snapshot retrieved November 7, 2026. The county totals add up to 9,889,704, matching the statewide total in the same dataset.
At the time of retrieval, the results were unofficial and subject to the canvass and certification process. Any material changes in certified results should be incorporated into the model before the research is considered final.
The 2024 county totals are drawn from the historical U.S. Senate county-results dataset retained for this analysis. The original source documentation should accompany the published research materials so readers can independently verify the baseline.
Step One: Calculating the Statewide Multiplier
The first calculation determines how the total number of Senate votes changed between 2024 and 2026.
The formula is:
F = 2026 statewide votes ÷ 2024 statewide votes
Substituting the actual totals:
F = 9,889,704 ÷ 11,291,854
F = 0.8758264143
This result is called the statewide multiplier.
A multiplier is a number used to adjust another number proportionally. In this case, the multiplier indicates that the 2026 statewide Senate vote total was approximately 87.58% of the 2024 total.
Why is this useful?
Counties cannot be compared fairly without accounting for the overall change in statewide voting volume. The multiplier establishes a common starting point for the model. It adjusts the historical county totals to reflect the statewide change between elections.
However, it does not assume that every county experienced exactly the same change. The next calculation accounts for differences in county size.
Step Two: Measuring County Size Using Natural Logarithms
The model uses a mathematical measurement called the natural logarithm, abbreviated ln.
A logarithm is a way of expressing the size of a number on a compressed scale. The natural logarithm is especially useful when working with data that ranges from very small values to very large ones.
Texas counties vary considerably in population and voting volume. Some counties report only hundreds or thousands of Senate votes, while the largest counties report hundreds of thousands.
If raw vote totals were used directly in every part of the statistical calculation, the largest counties could dominate the analysis. Using logarithms reduces that scale difference and allows the model to examine relative county size.
For each county, the model calculates:
ln(2024 county votes)
It then calculates a weighted mean of those logarithms.
A weighted mean is an average in which observations receive different levels of influence based on their assigned weights. In this model, each county’s 2024 vote total is its weight. Consequently, counties with more votes have greater influence on the statewide reference point.
The weighted mean logarithm in the model is:
12.3473626536
The model then subtracts this reference value from each county’s logarithm:
Xᵢ = ln(2024 county votesᵢ) − weighted mean ln(2024 county votes)
The symbol i identifies an individual county.
This calculation produces a centered county-size measurement, represented by Xᵢ.
A positive value indicates that a county is larger than the weighted reference point. A negative value indicates that it is smaller. A value near zero means the county is close to the reference point.
Centering the measurement allows the model to examine whether county size is associated with differences in vote retention.
Step Three: Calculating the County-Size Coefficient
The next calculation introduces a statistical term called a coefficient, represented by the Greek letter beta, or β.
A coefficient is a number that measures the relationship between a variable and the adjustment made by a mathematical model.
The model uses 10 designated counties as its calibration sample. A calibration sample is a group of observations used to estimate a model parameter. The remaining 244 counties are treated as a holdout group for examining how the model performs beyond the counties used to estimate that parameter.
For each of the 10 calibration counties, the model calculates the ratio of its actual 2026 votes to its 2024 votes. It then compares that ratio with the statewide multiplier.
The coefficient is calculated using:
β = Σ[Xᵢ × (2026 actualᵢ ÷ 2024 totalᵢ − F)] ÷ Σ[Xᵢ²]
The Greek capital letter sigma, Σ, means to add the specified values across the calibration counties.
The term Xᵢ² means the centered county-size measurement multiplied by itself.
In plain English, the calculation estimates whether counties that are larger or smaller than the weighted reference point tend to experience a different change in voting volume than the state as a whole.
The resulting coefficient is:
β = 0.0128185112
This is a relatively small coefficient. It means the model makes a modest adjustment to the statewide multiplier based on county size.
The 10 calibration counties we chose are: Floyd, Hansford, Henderson, Jackson, Lampasas, Nueces, Ochiltree, Presidio, San Augustine and Wise.
The selection of these counties is a methodological choice. The workbook identifies the counties but does not establish that they were randomly selected or constitute a statistically representative sample. That limitation should be considered when interpreting the model.
Step Four: Calculating Each County’s Modeled Vote Total
The statewide multiplier and county-size coefficient are combined to calculate an adjusted ratio for each county.
The formula is:
County ratioᵢ = F + (β × Xᵢ)
The model then multiplies that ratio by the county’s 2024 vote total:
Modeled votesᵢ = 2024 county votesᵢ × County ratioᵢ
The workbook applies two mathematical safeguards:
Modeled votesᵢ = MIN(2024 total, MAX(0, 2024 total × (F + β × Xᵢ)))
The MAX function prevents the model from producing a negative vote total. The MIN function prevents a modeled county total from exceeding its 2024 baseline.
These safeguards establish reasonable mathematical boundaries. They do not represent findings about what happened in any county.
Once the calculation is completed for all 254 counties, the modeled county totals add up to exactly 9,889,704—the actual 2026 statewide Senate vote total.
This is an intentional feature of the model. The statewide multiplier establishes the overall voting volume, while the county-size coefficient adjusts the distribution among counties.
The model therefore examines how the statewide total is allocated geographically.
Step Five: Measuring the Difference Between the Model and Actual Results
The next step compares each county’s modeled total with its actual reported 2026 total.
The difference is called a residual.
The formula is:
Residualᵢ = Actual 2026 county votesᵢ − Modeled votesᵢ
A positive residual means the actual county total was higher than the model calculated.
A negative residual means the actual total was lower than the modeled figure.
A residual of zero means the model and actual result match exactly.
Residuals are a standard part of statistical analysis. They measure the difference between a model’s estimate and the observed data.
For example, suppose a county’s modeled total is 10,000 votes, but its actual reported total is 10,500. The residual is positive 500.
If another county’s modeled total is 10,000 but its actual total is 9,500, its residual is negative 500.
The two counties have residuals of equal size but opposite direction.
A residual does not explain why the difference occurred. It simply identifies the amount and direction of the difference between the model and the reported result.
Possible explanations for county-level differences include changes in voter participation, population shifts, demographic changes, local political conditions and other factors not included in the model.
The model cannot determine which explanation applies to a particular county.
Step Six: Measuring the Model’s Accuracy
A statistical model should not be judged simply by whether its predictions look reasonable. Its errors must be measured consistently.
This research uses several standard statistical measurements.
Mean Absolute Error (MAE)
Mean Absolute Error measures the average size of the county-level differences between modeled and actual results.
The formula is:
MAE = (Σ |Residualᵢ|) ÷ 254
The vertical bars indicate absolute value. They mean that a number is treated as positive regardless of whether the original residual was positive or negative.
This is important because positive and negative residuals can otherwise cancel each other out.
MAE answers a straightforward question: On average, how many votes did the model differ from the actual result in each county?
A lower MAE indicates a closer average fit.
Root Mean Squared Error (RMSE)
Root Mean Squared Error measures the size of the model’s errors while placing greater emphasis on larger discrepancies.
The formula is:
RMSE = √[Σ(Residualᵢ²) ÷ 254]
Each county’s residual is squared, the squared values are added together, and the result is divided by the number of counties. The square root is then taken.
Squaring the residuals prevents positive and negative values from canceling each other out. It also makes large errors count more heavily than small ones.
For example, an error of 1,000 votes contributes substantially more to RMSE than an error of 100 votes.
RMSE is particularly useful when researchers want to know whether a model has a few unusually large county-level discrepancies.
Residual Standard Deviation
Standard deviation measures how widely a group of numbers is spread around its average.
In this analysis, residual standard deviation measures how widely the county-level errors are distributed.
A lower standard deviation indicates that the residuals are more tightly grouped. A higher value indicates greater variation.
Mean Absolute Percentage Error (MAPE)
Mean Absolute Percentage Error measures the average absolute error relative to each county’s actual vote total.
The calculation is:
MAPE = (1 ÷ 254) × Σ(|Residualᵢ| ÷ Actual votesᵢ) × 100
This measurement is useful because an error of 500 votes has a different significance in a county with 2,000 votes than in a county with 200,000 votes.
MAPE expresses the average error as a percentage, allowing comparisons across counties of very different sizes.
Each of these measurements provides a different view of model performance. No single measurement tells the entire story.
The Results: How Closely Does the Model Fit?
The completed model includes all 254 Texas counties.
The principal statewide figures are:
| Measurement | Result |
|---|---|
| 2024 statewide Senate votes | 11,291,854 |
| 2026 statewide Senate votes | 9,889,704 |
| Statewide multiplier | 0.8758264143 |
| Weighted mean logarithm | 12.3473626536 |
| County-size coefficient | 0.0128185112 |
| Counties analyzed | 254 |
| Total modeled 2026 votes | 9,889,704 |
The county-level model predictions sum to the actual statewide total. That makes it possible to examine how closely the model distributes the statewide voting volume among individual counties.
The unconstrained mathematical optimization identifies the following targets:
| Error measurement | Best-fitting modeled share |
|---|---|
| Mean Absolute Error | 99.423% |
| Root Mean Squared Error | 100.638% |
| Residual standard deviation | 100.696% |
These are mathematical optimization results. The latter two values exceed 100%, meaning they would allocate more votes than the actual statewide total.
For a model that must distribute exactly the number of votes reported statewide, the appropriate constraint is that modeled allocations cannot exceed 100% of the actual total.
Under that constraint, a 100% statewide allocation produces the lowest RMSE and residual standard deviation.
The model’s purpose is to distribute the known statewide total across counties, not to create an unexplained statewide shortfall or surplus.
Examining the 244-County Holdout Group
The research also examines the 244 counties that were not used to estimate the county-size coefficient.
This is called a holdout analysis. It provides an additional way to determine whether the model’s results are being driven primarily by the 10 calibration counties.
The holdout counties show a similar pattern: the model produces substantially closer county-level results when the full statewide total is allocated.
There is an important qualification. The holdout counties still share the statewide multiplier and weighted centering calculation, both of which use statewide information. Therefore, this is not a completely independent validation test.
It is better understood as a test of how the county-size adjustment performs outside the 10 counties used to calculate its coefficient.
What the Model Establishes—and What It Does Not
The analysis establishes several measurable facts.
First, the 2026 statewide Senate vote total was approximately 12.42% lower than the 2024 total.
Second, the model uses a consistent mathematical method to distribute the 2026 statewide total across all 254 counties, taking historical county voting volume and relative county size into account.
Third, the model produces county-level residuals that identify where actual reported results differ from the modeled distribution.
Fourth, the statistical measurements allow those differences to be evaluated consistently rather than relying on subjective impressions.
But the model also has limitations.
It does not identify individual voters or establish whether voters changed political preferences. It does not determine how many registered voters stayed home, how many first-time voters participated, or how migration affected a particular county’s election results.
It does not establish fraud, manipulation, misconduct or any other specific cause of a residual.
The model is retrospective because the known 2026 statewide total is used to establish the multiplier. Its purpose is to examine the distribution of reported votes, not to forecast an unknown statewide result.
The selection of the 10 calibration counties also deserves further examination. Because they are not documented as a random sample, the coefficient should not be treated as a universal measurement of how county size affects voting behavior.
These limitations do not make the model useless. They define what conclusions can responsibly be drawn from it.
Conclusion: Establishing a Baseline for Further Investigation
The value of this research is that it provides a consistent, county-by-county mathematical baseline for examining the 2026 Texas U.S. Senate election.
Instead of relying solely on statewide totals, the model considers the historical voting volume of each county, adjusts for the overall change between elections, and makes a modest statistical adjustment based on relative county size.
It then compares those modeled totals with the actual reported results.
The resulting residuals identify where further investigation may be useful. They do not independently explain the cause of the differences.
The next stage of research should examine additional information, including voter turnout, registration activity, population growth, migration, housing patterns and demographic changes.
By adding those variables, researchers can begin testing whether measurable changes in communities help explain the differences between modeled and actual county results.
The objective is not to force the numbers to support a particular conclusion. It is to establish a transparent methodology, identify what the available data can tell us, and determine what additional evidence is needed to understand the changing political landscape of Texas.
Research documentation: The 2026 county totals are from a Texas Secretary of State election-results feed snapshot retrieved November 7, 2026. Those results were unofficial at the time of retrieval. The 2024 county totals are from the retained historical U.S. Senate county-results dataset used in the model. The accompanying Excel workbook, “Texas U.S. Senate County Model — Final Reconciled Analysis,” contains the county-level calculations, formulas, sensitivity analysis and methodology notes.
We encourage you to seek out original sources and verify your own data.




Senate Race in Texas – The Statistical Model by County
What Do 254 Texas Counties Tell Us About the 2026 U.S. Senate Election? A Mathematical Model Examines the Numbers An...

Granbury Recall: Five Targets, Three Lawsuits, One Mess
Granbury, TX – Granbury taxpayers are now financing a legal fight against the very recall process designed to give them...

Beyond Paxton: The Other Republican Losses That Turned Texas Blue
Texas, USA – The November 3, 2026, Texas Republicans losses were considerably worse than just Ken Paxton‘s defeat by James...
You must be logged in to post a comment Login